Blog topic
AI engineering
Agents, evals and retrieval, written from systems I have built and run.
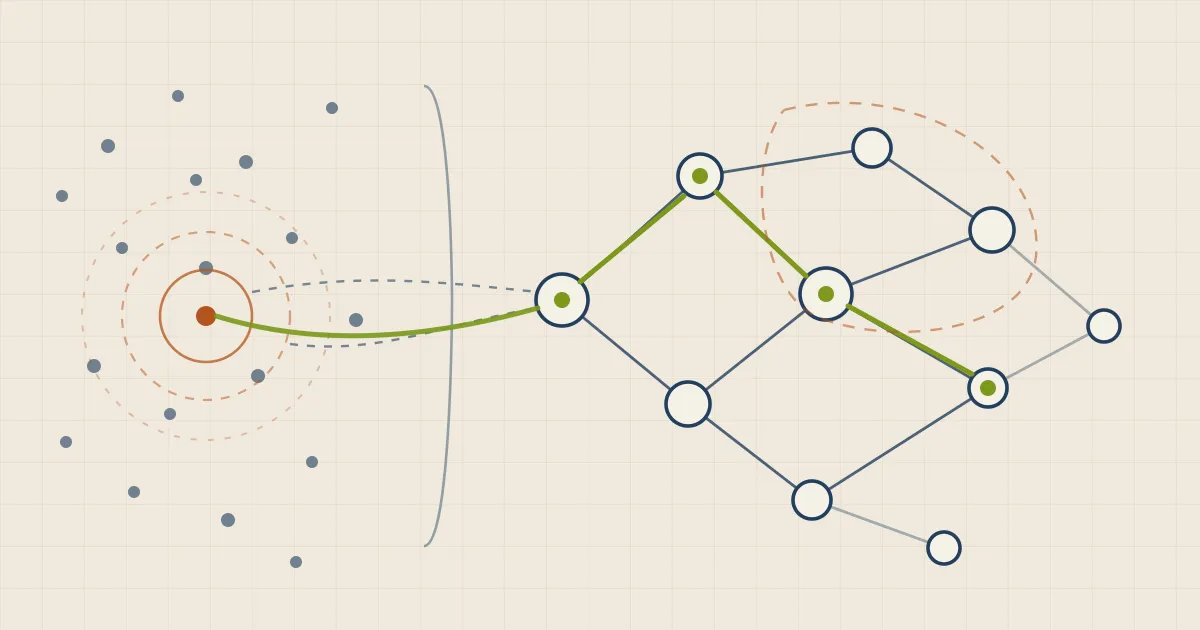
When GraphRAG earns its extra complexity
Vector search finds similar passages. A graph can connect people, events, and dependencies across many passages. The useful question is when you need both.
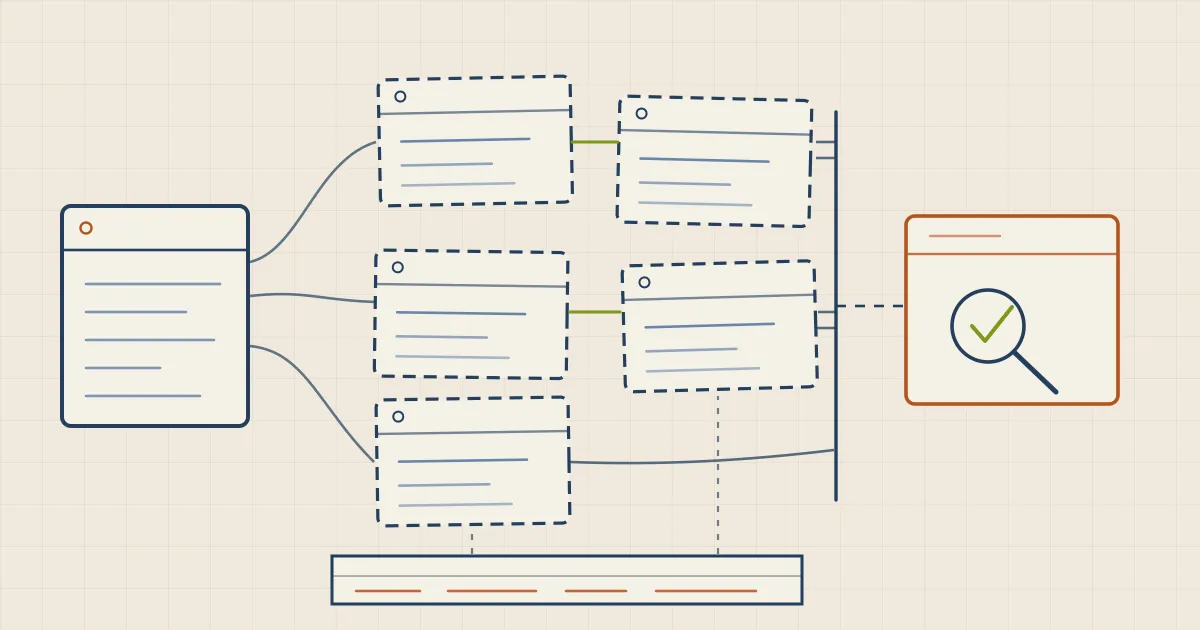
Why long tasks need workflows, not longer contexts
A task that fails in one long conversation often succeeds when it is split into isolated subagents with explicit success criteria, external state, and an independent reviewer.
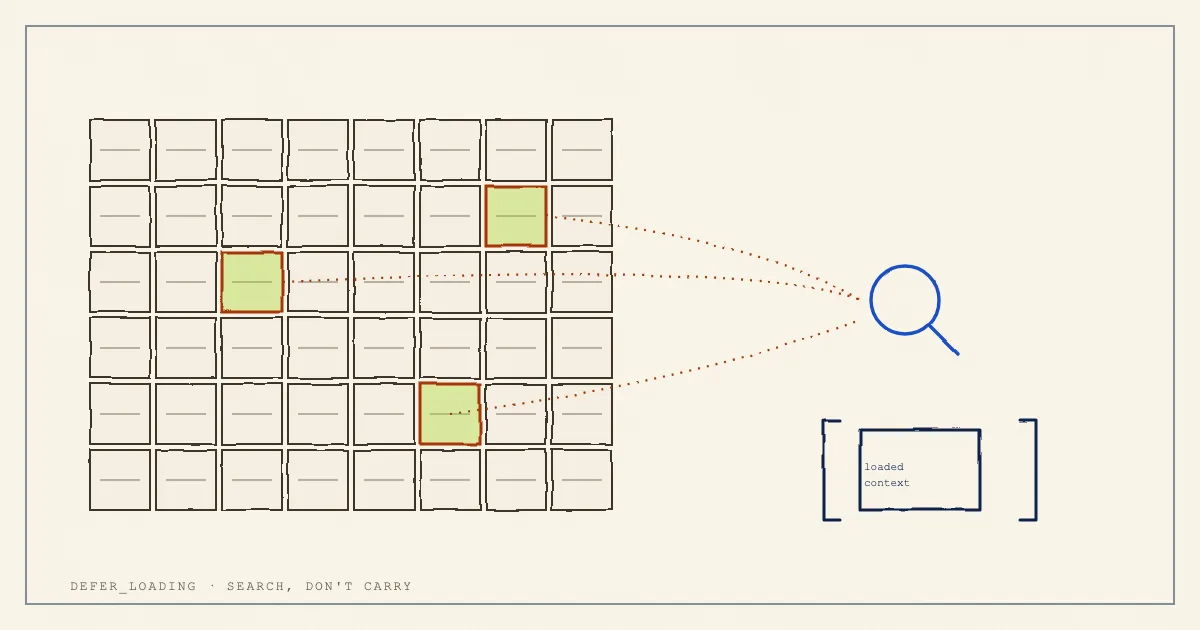
More agent tools, less context with defer_loading
Loading every tool definition upfront wrecks tool recall once an agent has more than a handful of tools. Anthropic's defer_loading keeps tools discoverable without bloating context, here's when it's worth using.
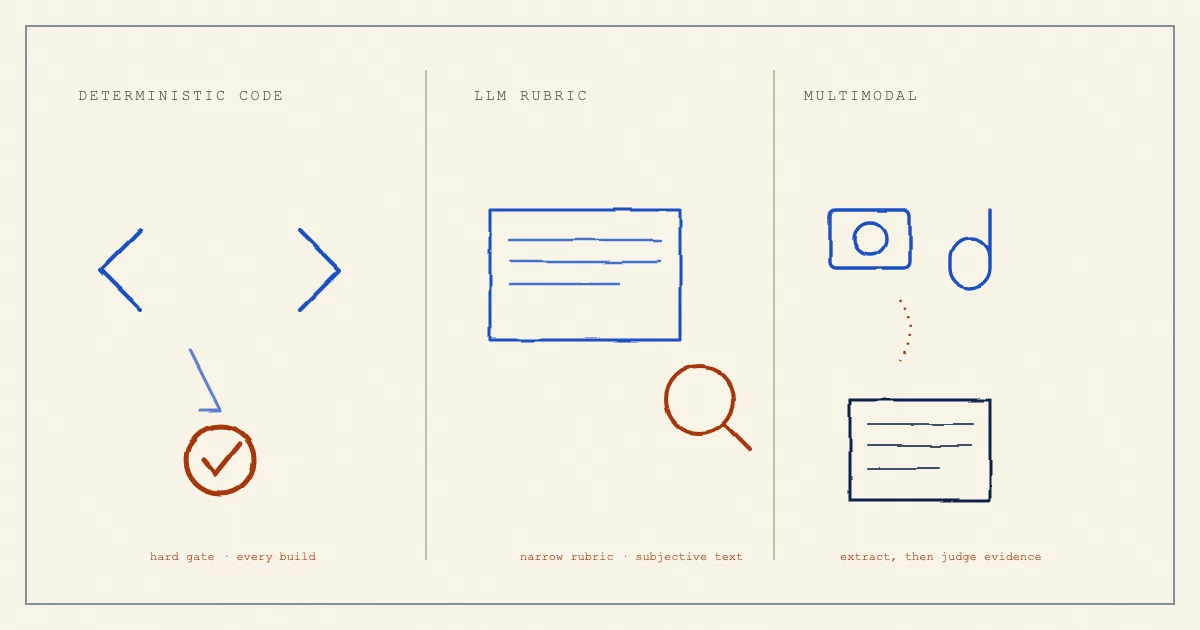
Production evals are three systems, not one
Treating evals as one pipeline is why they're slow and expensive. Splitting deterministic checks, LLM rubric judges, and multimodal extraction into three systems is what I run in production.
Why I run evals before every agent deploy
A small, representative eval baseline in CI catches the regressions that manual spot-checking misses. Here is how I size the set and what I actually measure.